
I Went Looking for Broken Pages. Something Else Was Looking Through My Website.
Website 404 errors can reveal more than broken links. Sometimes they reveal automated systems requesting pages that never existed, and the difference matters when you’re trying to maintain a healthy website and make sense of your traffic.
I recently went looking for 404 errors on my own website. What started as a routine cleanup turned into a much more interesting investigation about who, or what, might be visiting my site.
Why Was I Investigating 404 Errors?
I regularly look at website performance, search visibility, traffic, and the technical issues that can interfere with a visitor’s experience. A 404 error is one of those things worth investigating because it means someone requested a page the server couldn’t find.
Sometimes the explanation is simple. You changed a URL, removed an article, or somebody linked to a page incorrectly. Those are problems you can usually identify and fix.
But during my investigation, I started noticing requests for pages that had never existed on my website.
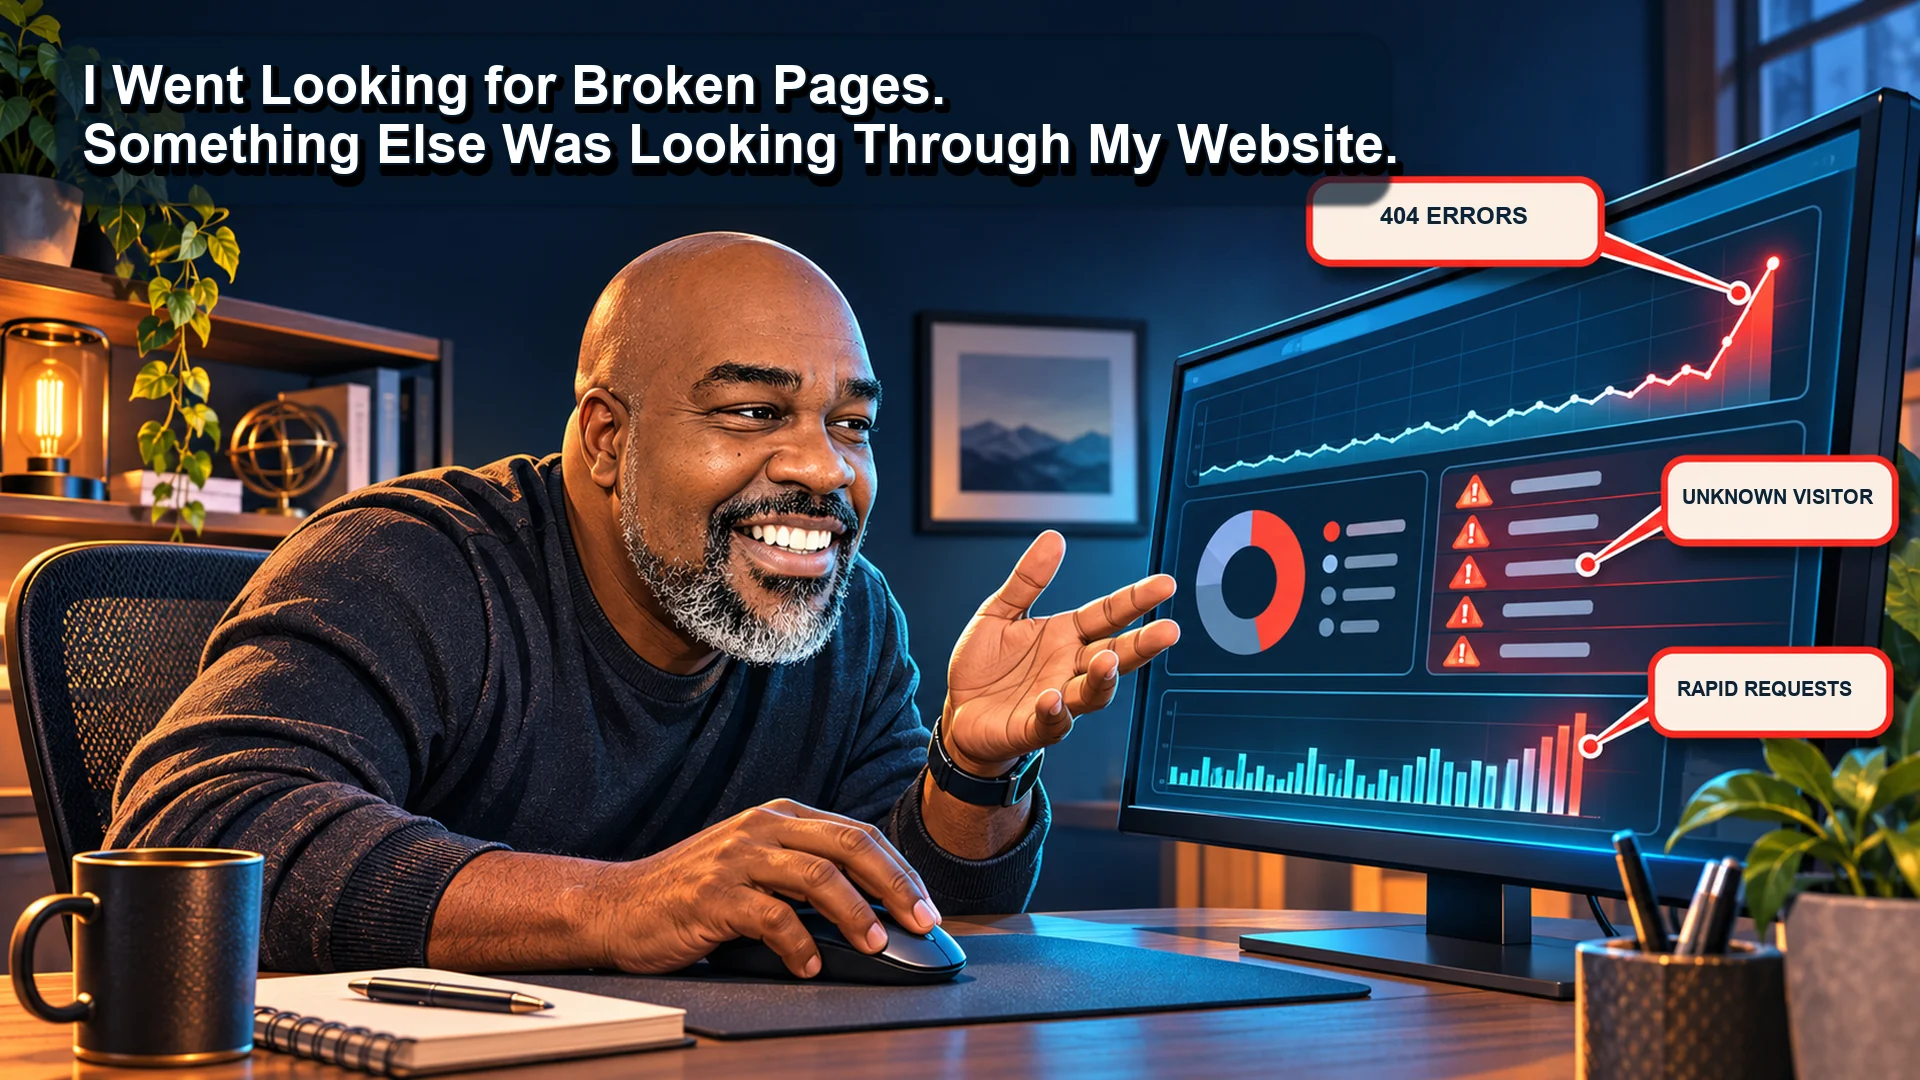
The requests appeared to be happening at an unusually rapid pace. This didn’t look like an ordinary visitor clicking through my navigation, getting lost, and trying another page.
It looked like something was searching for pages.
And I wanted to know why.
What Does It Mean When Bots Request Pages That Never Existed?
A website can receive requests for URLs that were never part of its navigation, sitemap, or published content. Automated crawlers and scanners can generate requests by following discovered links, testing common paths, or guessing possible URLs.
Think about your website as a physical business. You have a front door, a reception area, offices, and rooms that serve particular purposes.
Now imagine someone walking around the outside of your building, trying doors you never installed, checking for windows that aren’t there, and looking for a basement entrance you don’t have.
You might initially think you have a problem with your building.
But the more important question is why somebody keeps looking for entrances that never existed.
Your website can experience something similar.
Automated systems don’t necessarily limit themselves to the pages you publish. They can request addresses that follow common patterns, resemble WordPress directories, or look like administrative and configuration paths.
Some are legitimate crawlers. Others may be vulnerability scanners or poorly behaved automation. The missing pages alone don’t tell us which one we’re dealing with.
Could AI Agents Be Responsible for These 404 Errors?
Yes, an AI agent could generate requests to nonexistent pages, particularly when it uses browser automation or attempts to navigate to an inferred URL. But a burst of 404 errors doesn’t prove that artificial intelligence is responsible.
This distinction is important because people tend to put all automated website activity into one category: bots.
Traditional bots have been crawling and testing websites for years. Search engines use them to discover information. Security researchers use automated tools to investigate vulnerabilities. Attackers also use scanners to find weaknesses.
AI introduces additional ways for software to interact with websites.
An AI assistant may retrieve content, operate a browser, follow links, or navigate to a URL it believes should exist. In some circumstances, the URL may be incorrect or based on an assumption rather than an actual page.
The challenge is that a request generated by an AI agent may not announce itself as an AI request.
That doesn’t mean every unidentified bot is an AI agent.
It means our existing methods for understanding website visitors deserve a closer look.
I’ve written previously about how AI agents are changing business websites. My 404 investigation raised a related question: What happens when those systems interact with a website in ways we don’t immediately recognize?
Can AI Agents Look Like Human Visitors in Google Analytics?
An AI-controlled browser can sometimes generate analytics events that resemble ordinary human activity. But not every bot or AI agent gets counted as a user, and Google Analytics does not simply record every request a website receives.
Here’s the distinction.
Google Analytics 4 collects activity through its measurement system. If an automated browser loads a page and executes the tracking code, it may produce measurable events.
Google also automatically excludes traffic from known bots and spiders. However, that doesn’t mean every automated visit is automatically identified.
Some agents operate through conventional browsers. Others fetch page content without executing the JavaScript required for standard GA4 tracking.
That creates three important possibilities:
A request appears in server logs but never appears in GA4.
Automated browser activity generates analytics events and may resemble ordinary visitor behavior.
A known bot is recognized and excluded from analytics reporting.
And there is another distinction business owners should understand.
A person clicking a link supplied by an AI assistant is a real visitor, even if the referral came from an AI platform. That’s different from an AI agent visiting your website on that person’s behalf.
If you’re trying to evaluate your website’s marketing performance, those differences matter.
Why Doesn’t Google Analytics Tell Me Everything About My Website Traffic?
Google Analytics measures website interactions. It is not a complete record of every HTTP request arriving at your server.
A server or content delivery network can receive requests for files, pages, and endpoints without a GA4 event ever being generated.
That is why website owners should understand the difference between analytics reports and server logs.
Think about the security cameras at a retail store. One camera might show people entering the showroom. Another might record activity at the loading dock or around the building.
If you only watch the showroom camera, you could miss what’s happening elsewhere on the property.
GA4 is useful for understanding measured visitor behavior, engagement, and conversions. Server and CDN logs can help explain requests that might never appear in those reports.
Even a GA4 report showing visits to a 404 page doesn’t necessarily represent every 404 response the server returned. It depends on how the website and tracking have been configured.
This is especially relevant when you’re investigating high volumes of requests to nonexistent pages.
Should You Fix Every 404 Error? How to Fix the Ones That Matter
No. Not every 404 error needs a redirect, replacement page, or immediate repair. In fact, a properly returned 404 is sometimes exactly what your website should provide.
Google explains in its 404 error guidance that URLs which never existed generally don’t need to be fixed simply because they were requested.
That was an important distinction in my investigation.
If an actual article moved to a new address, a permanent redirect may be appropriate. If somebody linked to the wrong URL, correcting that link makes sense.
But if an automated scanner requests a nonexistent configuration file or an imaginary page, creating a redirect doesn’t solve the underlying issue.
You may actually make your website harder to understand by redirecting unrelated missing URLs to your homepage.
And imagine spending hours creating redirects for a list of imaginary pages while the automated system keeps inventing new ones.
That’s a lot of work to accomplish absolutely nothing.
A 404 is not automatically evidence that your website is broken.
Sometimes it means your website correctly refused a request for something that isn’t there.
How Can You Tell Whether 404 Errors Are Bot Traffic?
The best starting point is to examine the actual requests, their timing, and the URL patterns. A large number of 404 errors can suggest automation, but identifying the source requires additional evidence.
Here are the things I would investigate.
Are the requested URLs real pages?
Start by separating legitimate website URLs from addresses that never existed.
Look for older articles, renamed pages, incorrect internal links, and common misspellings. Those may warrant correction.
Then look at the requests that don’t make sense for your website at all.
How quickly are the requests happening?
An ordinary visitor may encounter a missing page, try another link, and continue browsing.
Automated software can issue many requests in rapid succession.
If you see a high volume of requests hitting unrelated nonexistent URLs within a short period, that pattern deserves investigation. It is an indicator of possible automation, not conclusive identification of a bot.
What kinds of URLs are being requested?
The requested paths can provide useful clues.
Requests for nonexistent articles may suggest broken links, content discovery, or guessed URLs.
Requests for unfamiliar administrative paths, configuration files, or known software endpoints may indicate vulnerability scanning.
The purpose of the requests matters more than the number of errors alone.
What do the server or CDN logs reveal?
Compare timestamps, requested paths, response codes, IP information, user-agent strings, and request rates where available.
A common user-agent or IP address does not prove that requests came from one human or one bot, but these details can help identify patterns.
Services such as Cloudflare offer bot traffic analysis and request scoring on supported plans. These can help distinguish likely automated activity from normal visitor traffic.
For business owners who don’t manage server logs themselves, this is a good reason to involve their hosting provider or website support team.
Could Bot Traffic Be Distorting Your Marketing Reports?
Potentially, yes. Automated activity that escapes bot filtering and generates analytics events can affect the numbers you use to evaluate website performance.
Imagine reviewing a website that suddenly receives substantially more traffic.
At first glance, that sounds like great news.
But what happens if some of those recorded visits are automated browsers rather than prospective customers?
Your engagement figures and conversion rates may become harder to interpret. A traffic increase could lead you to believe a marketing initiative is working when the underlying visitor activity tells a different story.
That is why I keep coming back to the difference between traffic and results.
Website visits don’t automatically equal customers. And not every recorded visitor is necessarily a person considering your product or service.
I’ve discussed this broader measurement challenge in how to measure AI traffic and conversions in GA4.
The more automation becomes part of everyday internet activity, the more important it becomes to understand what your analytics actually measure.
Online Presence Readiness Assessment
Is your business ready to market online?
Answer 20 quick questions while we scan your website for tracking, ad pixels, structured data, search basics, speed and contact paths. Get a scored readiness report, free.
What Should a Business Owner Do About Suspicious 404 Activity?
Start with investigation, not redirects or aggressive blocking. You want to distinguish harmless missing-page requests from scanning behavior that may warrant protection.
Here is the approach I recommend:
✓ Review the missing URLs. Identify legitimate broken links and separate them from paths that never belonged to your website.
✓ Look for request patterns. Compare timestamps, URL structures, user agents, and request volumes using the logs available through your hosting or CDN provider.
✓ Check your analytics configuration. Understand how 404 pages are tracked and whether your reports are showing actual page interactions rather than every server error.
✓ Review your website security. Look for unusual requests targeting administrative or sensitive paths. Check your security monitoring and applicable hosting protections.
✓ Avoid indiscriminate blocking. Legitimate search crawlers and automated services may be important for discovery, monitoring, and accessibility. Blocking everything that looks automated can create new problems.
✓ Fix what actually needs fixing. Correct broken internal links, redirect genuinely moved content, and let nonexistent pages return appropriate 404 responses.
If the patterns suggest high-volume scanning or an attempted attack, review your available security controls and escalate to your hosting or security provider.
For ongoing website care, the goal isn’t to eliminate every 404. It’s to understand which errors reflect genuine problems for visitors.
That is part of what I mean by website maintenance, support, and optimization. Keeping a website healthy involves more than updating plugins and checking whether the homepage loads.
Does This Mean AI Is Becoming a New Kind of Website Visitor?
AI agents are creating new ways for software to interact with websites. They can navigate pages, retrieve information, and sometimes complete tasks using browser interfaces that were originally built for people.
But it would be a mistake to interpret every unexpected website request as evidence of AI.
The internet already has an enormous variety of automated systems operating on it. AI adds another category of behavior that website owners and analytics professionals need to understand.
For small businesses, the practical challenge is learning to distinguish actual customers from automated activity while keeping websites accessible to legitimate discovery systems.
That requires better observation, not more assumptions.
Frequently Asked Questions About Website 404 Errors and Bots
Can bots cause hundreds of 404 errors?
Yes. Automated scanners and crawlers can request many nonexistent URLs in a short period. The number of requests alone does not identify the software or establish malicious intent.
Can a bot visit pages that aren’t in my sitemap?
Yes. A sitemap helps search engines discover URLs, but it doesn’t restrict what another visitor or automated system can request. Crawlers can follow links or generate URL guesses independently.
Does Google Analytics automatically filter bots?
GA4 automatically excludes known bots and spiders. However, not all automated browser activity is guaranteed to be recognized, and requests that don’t execute analytics tracking may never appear in GA4.
Do 404 errors hurt my Google rankings?
Ordinary 404 responses for genuinely nonexistent pages do not inherently harm your site’s search performance. Problems arise when important pages are accidentally unavailable, internal links are broken, or the server returns incorrect status codes.
Should I redirect unknown 404 URLs to my homepage?
Generally, no. A redirect should lead to a relevant replacement page. Redirecting unrelated nonexistent URLs to the homepage can create confusing behavior for visitors and search engines.
The Lesson I Learned From Looking for Broken Pages
I went into this investigation expecting to find pages I needed to fix.
Instead, I found requests for pages that never existed, arriving in a pattern that raised questions about automated activity.
I haven’t established whether those requests came from conventional bots, security scanners, AI agents, or some combination. But the experience reinforced something I’ve believed for years.
Managing your online presence requires understanding what is actually happening, not just responding to whatever a dashboard reports.
Remember the building with all those imaginary doors?
Before you call a contractor to repair them, find out who’s walking around looking for them.
A 404 error tells you a page wasn’t found. It doesn’t tell you why somebody was looking for it.
That’s where the real investigation begins.
If you’re seeing strange website traffic, unexplained 404 errors, or analytics that don’t seem to match your actual business activity, start by understanding what your website is recording.
Take the Free Online Presence Readiness Assessment to identify areas of your website and measurement setup that may need attention.
Last fact-checked: November 4, 2026.